Seasonality Controls in Ecommerce Conversion Experiments
Match test periods to the calendar to separate seasonal swings from real treatment effects.
Seasonality controls in ecommerce conversion experiments separate changes in shopper intent from changes caused by the treatment. With conversion rates swinging substantially across a calendar year, an uncontrolled comparison can reward an ineffective change or reject a useful one. For results teams can trust, they need seasonal baselines that match, fixed stopping rules, audiences with a similar mix, holdouts that fit the test and clean session counts.
Why seasonal swing makes raw conversion rates unreliable as experiment inputs
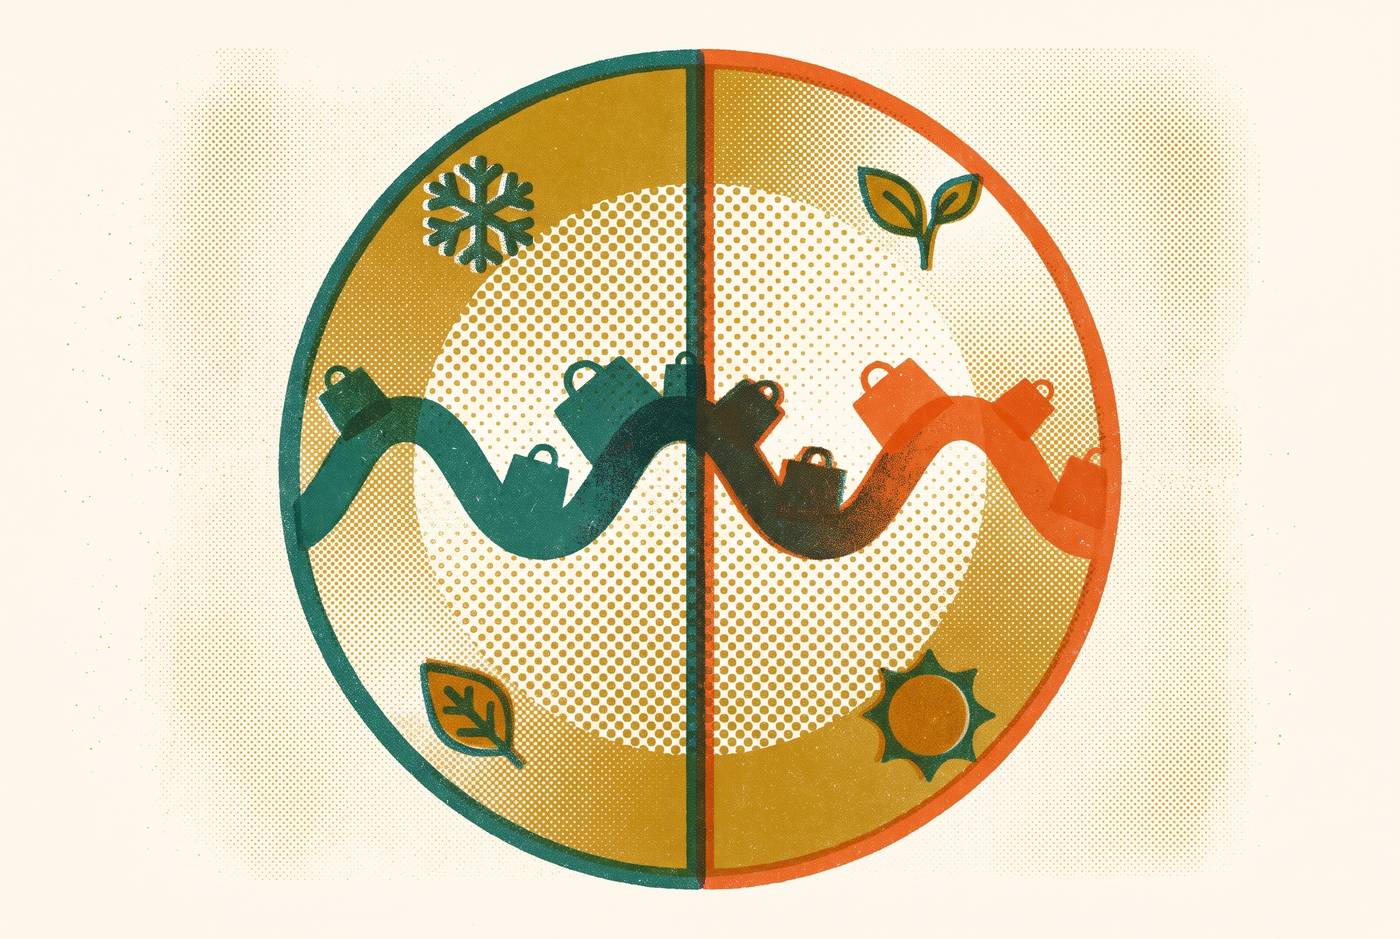
November and April describe very different buying environments, even when a store makes no changes to its site. Dynamic Yield's benchmark series across October 2025 to September 2026 shows the global average conversion rate peaking in November 2025 and reaching its low in April 2026. The intervening movement reflects shopper behavior and promotional calendars. The baseline moves before any treatment is applied. Teams need to know where a raw rate falls in the calendar before they use it as an experiment input.
BFCM lifts Q4 conversion because shoppers arrive with stronger purchase intent and discounts create urgency. Those conditions can raise conversion even when navigation, product pages and checkout have stayed the same. Conversely, their absence can lower the rate without introducing new friction. Seasonal changes also vary by vertical, with beauty and food converting at far higher rates than luxury and jewelry even in slow months, so peer benchmarks also differ in the mix of shoppers they reflect.
Traffic growth can obscure this mechanism further. A store may get far more visitors while its conversion rate falls because more of the shoppers who arrive with the season are lower-intent, changing the denominator even if the funnel stays the same. Device mix can also affect the rate when the extra traffic changes the balance of mobile and other sessions. Treating the blended decline as evidence of a conversion problem mistakes a change in who arrived for a change in how well the site served them.
How an uncontrolled experiment misreads seasonal movement as test signal
The error becomes an experiment finding when a team credits the variant with movement that came from the calendar. A test begun in November and read in January crosses a sharp seasonal decline. If the team compares the variant's later conversion rate with the earlier high-season baseline, the comparison mixes treatment performance with the loss of holiday intent. The variant can appear to have damaged conversion even if the change did nothing, creating a false drop.
The reverse occurs during a rising seasonal period. A later measurement can reward an ineffective change because more visitors are ready to buy. The crucial failure is the uncontrolled comparison. Merely calling an exercise an A/B test does not make a before-and-after reading causal, while a simultaneous comparison with comparable audiences is not equivalent to comparing November with January.
For a historical baseline, the relevant comparison is the same calendar week in the prior year. Comparing December with June describes seasonality. Even a well-matched historical period, however, cannot make a single observation into a trend. One week can capture a particular concentration of intent or promotional activity. Declaring a winner from that snapshot turns the experiment into a seasonal bet.
Three additional confounds that compound seasonal distortion in 2026
When bot sessions, AI agent crawls and other known non-human traffic enter the session count, changes in their volume can appear as changes in conversion. The measured audience is no longer just shoppers. A seasonal increase in this traffic can depress a blended rate without showing that human visitors became less willing to buy. This is a traffic-quality problem layered onto the seasonal one.
AI-referred human sessions create a different complication because they can bring unusually strong intent. Shopify's Q1 2026 data shows that AI-referred shoppers convert at much higher rates than organic search visitors on product pages, and more than half arrive directly on product pages. These are not interchangeable with crawler sessions. Their arrival changes the distribution of human purchase intent, and a growing share can raise aggregate conversion independently of the experiment. Because this is a structural shift rather than a seasonal one, matching calendar weeks alone cannot remove it.
Device-mix shifts create the third confound by changing the population represented in the aggregate rate. Channel changes can compound that shift when a store scales paid spend into a seasonal peak. The audience is not static during the test. Visitors in week four may differ from those in week one in their arrival channel, device and purchase intent. If a result overlooks those differences, it can mix the effect of the treatment with several changes in who visits the store at the same time.
The five controls that isolate true test signal from seasonal noise
Control one is a same-week year-over-year baseline. Teams should compare the test period with the same calendar week in the prior year. This aligns the seasonal position of the historical comparison instead of treating a moving calendar as a stable baseline. It requires at least one full year of clean historical data segmented by week. Without that history, the gap should be explicit. A month-over-month comparison is not a substitute, and changes in traffic composition still need separate controls.
Control two is a pre-set minimum run duration. The experiment should run long enough to reach its pre-set sample size and cover at least one full weekly cycle, typically two to four weeks for mid-traffic stores. The stopping rule belongs before the launch. Stopping when an early result looks favorable can capture a day-of-week effect and label it a treatment effect. Pre-registering the rule removes the discretion to end the test at its most flattering moment.
A fixed duration also needs a seasonal boundary. Extending the window merely to accumulate enough observations can pull the test across a sharp change in purchase intent. More data does not resolve that mismatch. If the required sample cannot be reached within a suitable window, the honest options are to accept an underpowered result or pause and restart. A stopping rule should not become a reason to combine periods that answer different questions.
Control three is audience stratification before randomization. Teams should group visitors by intent signals, including whether they are new or returning, their arrival channel and their device, so each variant gets a similar mix. This addresses composition at the point of assignment. A seasonal surge of cold mobile traffic should not land disproportionately in one variant while the other receives more returning visitors. Otherwise, the experiment compares audiences as well as treatments, leaving an apparent lift partly attributable to who entered each group.
Control four is to use holdout and geo-lift design for channel-level tests. For a channel or feature, rather than a page element, teams can apply the treatment in matched markets and compare revenue with markets held back from it. The comparison gives an estimate of incrementality without relying on a seasonal rise in aggregate conversion. The distinction is especially important for AI-channel and on-site assistant tests. Shoppers who engage an assistant are self-selected and higher-intent, so their stronger conversion is not, by itself, proof of incremental lift.
A proper holdout separates that selection effect from the treatment comparison. It also avoids treating an aggregate seasonal movement as the channel's contribution. For more developed measurement programs, calibrated Bayesian models can feed incrementality experiment results back into channel contribution estimates. The experiment supplies the calibration rather than merely endorsing an attribution report. This strengthens channel measurement without making the assistant-engagement group a valid control for itself.
Control five is clean denominator filtering. Teams should remove bot sessions, AI agent crawls and known non-human traffic before they calculate the baseline rate, then keep segmented denominators for the whole experiment. Paid sessions should remain distinguishable from organic, and AI-referred sessions from direct. A single blended rate hides those shifts. Segment-level measurement makes it possible to distinguish a change within an audience from a change in how much that audience contributes to the total.
The analytics method must also remain consistent. Shopify changed how it measures sessions on September 21, 2026, so pre-change and post-change session-based data are not directly comparable without recomputation. That break affects the measurement baseline itself. A team comparing periods across that break cannot assume that a change in conversion comes from shopper behavior or the treatment. A usable denominator needs both clean traffic filtering and a way of measuring sessions that stays the same.
When traffic is too low for a clean A/B test during a seasonal window
Low traffic can make the required sample unattainable before the seasonal window closes. For many DTC stores, that is a practical constraint during off-peak months that can persist even with a longer test. An underpowered experiment cannot support a confident winner. Forcing a binary decision from it can be worse than having no test because the result gives weak evidence the appearance of authority. The appropriate response is to change the evidence used for the decision while maintaining the standard for claiming a lift.
In that position, teams should ship high-confidence UX fixes derived from qualitative research and measure before and after with careful seasonality controls. Session replay, exit surveys and usability tests can reveal friction without the need for a large randomized sample. The claim must remain narrower than an experimental finding. A controlled historical comparison can help interpret the outcome, but it does not turn qualitative evidence into a clean A/B estimate.
Behavioral simulation is another way to learn before a theme change goes live. Shopify's SimGym lets merchants obtain feedback from AI shoppers that simulate buyer behavior, helping identify navigation and storefront friction. Such feedback serves hypothesis development. Seasonal troughs also give teams a useful window to build a friction map from heatmaps, scroll depth, rage clicks and post-purchase surveys. That work prepares higher-confidence hypotheses for testing when traffic recovers.
Baymard's checkout research provides a validated checklist of common friction points, including forced account creation, hidden shipping costs and a long checkout. These can help teams make high-confidence fixes without running a live experiment for every decision. The research narrows the search for actionable problems. Combined with the store's qualitative evidence, it supports work on identifiable obstacles rather than speculative changes prompted by a falling aggregate rate.
Reading results honestly once the controls are in place
A controlled experiment supports a decision about its treatment and tested audience. Teams should document winners and losers, then queue the next test. Reliable decisions accumulate across an experiment program. The size of one lift is less useful than a record that preserves what changed, which audience was tested and how the result was measured. That record also prevents an attractive seasonal result from becoming an unquestioned benchmark.
Platform-reported ROAS and last-click attribution systematically overstate true performance, particularly during seasonally elevated periods when BFCM conversion can mask signal loss. Platform numbers are not independent validation of lift. Experiment findings should instead be cross-checked against an incrementality estimate. Post-purchase “how did you hear about us” surveys remain useful here because they do not depend on the cookies and pixels whose degradation makes platform attribution unreliable.
A shopper who resolved objections through an AI assistant before arriving on-site can behave more like a returning customer than cold acquisition. If AI-referred sessions are overrepresented in the treatment group, the observed conversion advantage may be real while remaining partly structural. It is not purely evidence for the tested change. Trustworthy reporting distinguishes that audience advantage from incremental lift, leaving the experiment to support only the conclusion its controls can defend.